

Checks and Tests
Rocky checks a model at four points. Each point runs different checks and has a different cost. Start with this table.
| Check | Config | Runs at | Needs | Cost |
|---|---|---|---|---|
| Contract | {model}.contract.toml |
rocky compile |
Nothing | Compares the inferred schema. Reads no rows. |
| Model execution | None | rocky test, rocky ci |
Nothing | Runs each model on in-memory DuckDB. |
| Unit test | [[test]] |
rocky test |
Nothing | Runs one model on DuckDB per test, with your fixtures. |
| Declarative test | [[tests]] |
rocky test --declarative |
rocky.toml and a reachable warehouse |
One SQL query per assertion. |
| Pipeline-level check | [pipeline.<name>.checks] |
rocky run, rocky apply |
The warehouse | A few queries per table. See each check. |
| Assertion | [[assertions]] |
rocky run, rocky apply |
The warehouse | One SQL query per assertion. |
| Cross-source overlap | checks.cross_source_overlap |
rocky run |
The warehouse | One UNION ALL query per sibling group. |
rocky compile ──► contracts E010 E011 E012 E013 E014 │ an error withholds the model and its downstream ▼ rocky test ─────► model execution + [[test]] unit tests (DuckDB, local) rocky test --declarative ──► [[tests]] (your warehouse) │ rocky ci = compile + model execution, in that order │ ▼ rocky run / apply ► pipeline-level checks, then [[assertions]] both write check_results[], one shape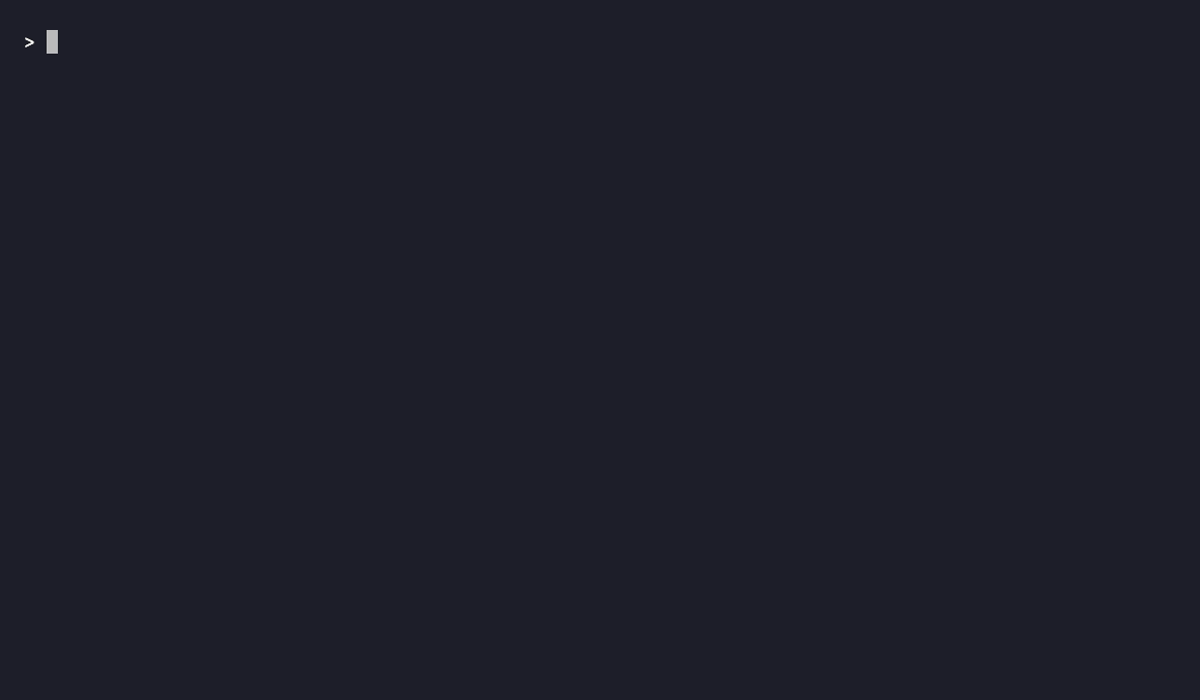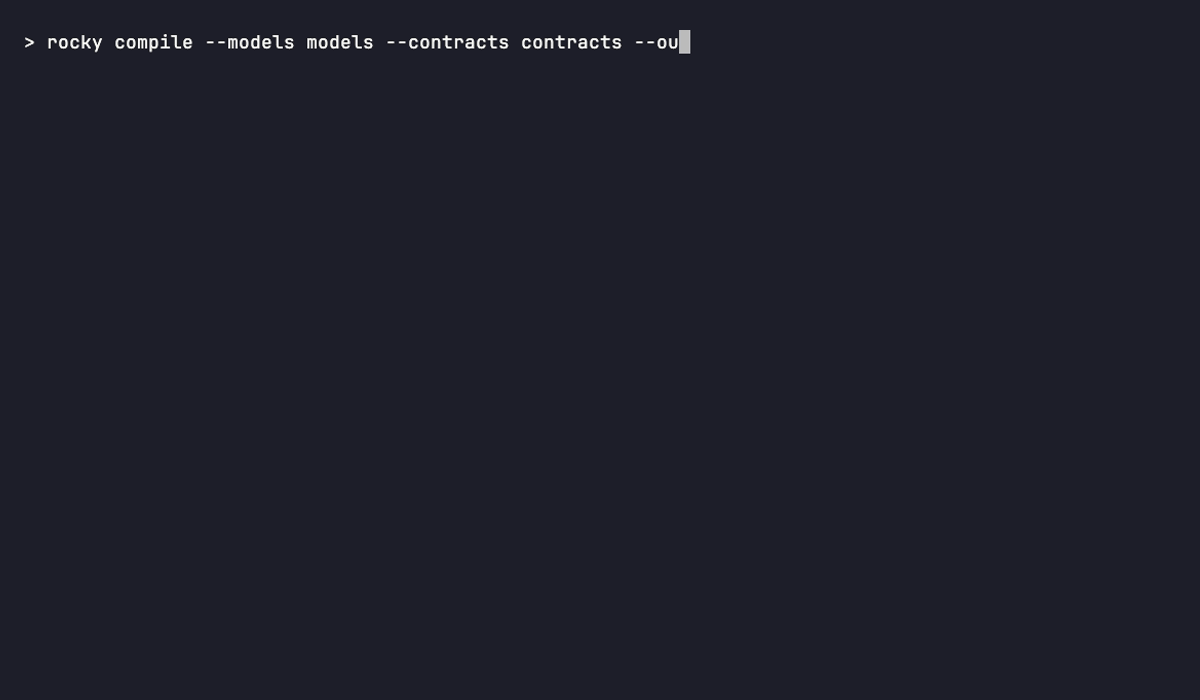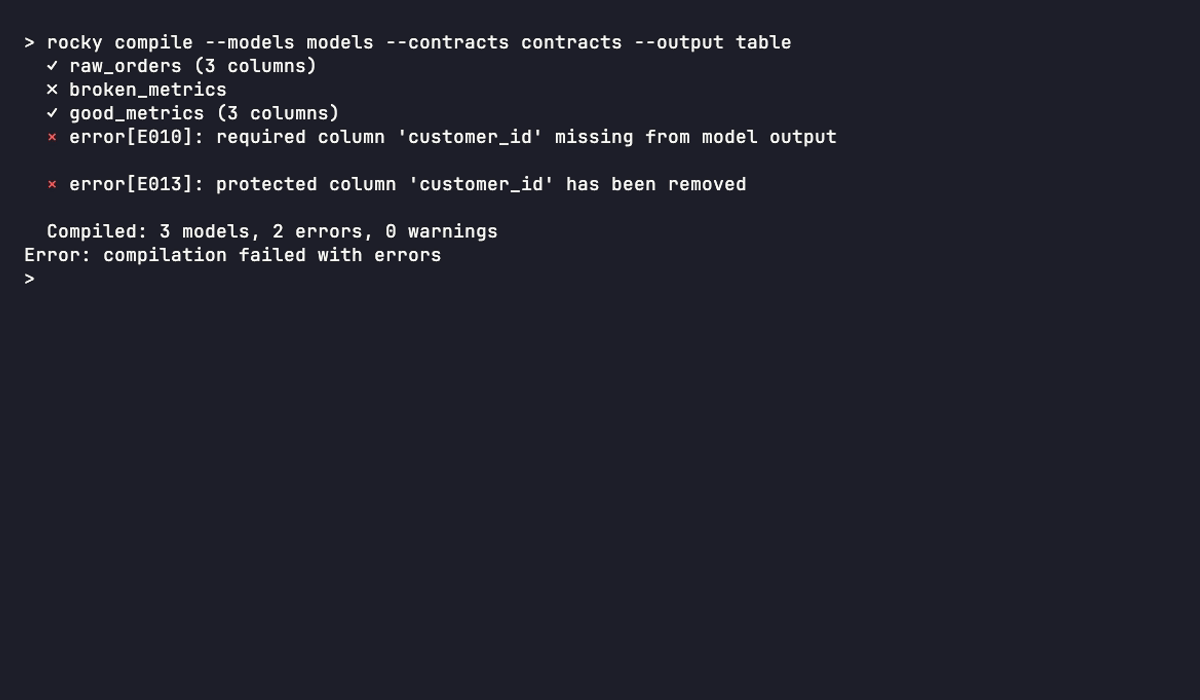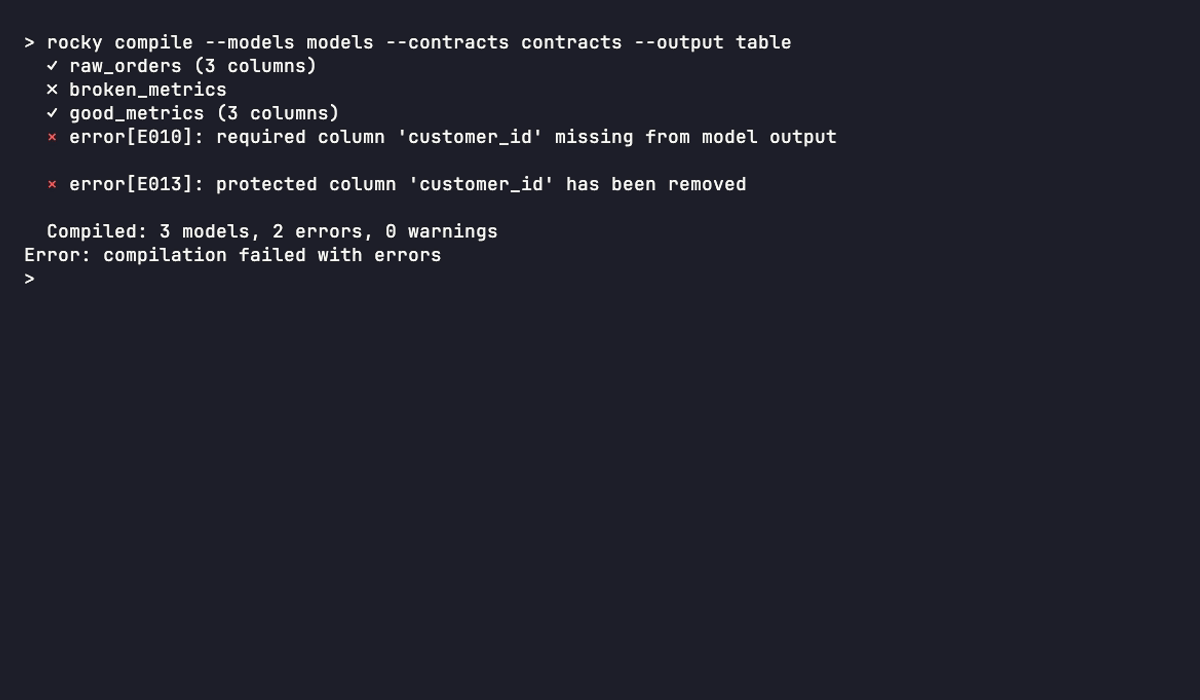
Assertions run on every pipeline type, replication included. A target table doubled by the same source arriving twice is caught at load time.
Two blocks differ by one letter. Do not mix them up.
| Block | Where | What it checks | Runs |
|---|---|---|---|
[[test]] (singular) |
model sidecar | Model logic against fixtures you supply | Locally on DuckDB, with rocky test |
[[tests]] (plural) |
model sidecar | Rows already in the warehouse | rocky test --declarative, against the warehouse |
[[assertions]] |
[pipeline.<name>.checks] |
Rows already in the warehouse | Inline during rocky run and rocky apply |
Data contracts
Section titled “Data contracts”A data contract declares what a model’s output schema must look like. The compiler compares the schema it inferred against the contract. It catches a missing column, a wrong type, and a nullability violation before any row is written.
A contract is a {model_name}.contract.toml file. The compiler reads it from two places:
- Next to the model file, as
<model>.contract.toml. - The project
contracts/directory beside the models directory.--contracts <DIR>replaces this directory.
A file in the directory wins over a file next to the model. The example below is such a file:
[[columns]]name = "customer_id"type = "Int64"nullable = falsedescription = "Unique customer identifier"
[[columns]]name = "total_revenue"type = "Decimal"nullable = false
[rules]required = ["customer_id", "total_revenue"]protected = ["customer_id"]
Each [[columns]] entry takes name (required), type, nullable, and description. If nullable = false, the column must be non-nullable. description is for readers and is not validated. Type names match the RockyType variants: Boolean, Int32, Int64, Float32, Float64, Decimal, String, Binary, Date, Timestamp, TimestampNtz, Array, Map, Struct, Variant.
[rules] key |
Effect |
|---|---|
required |
These columns must exist in the output. A missing one is E010. |
protected |
These columns must never be removed. A removed one is E013. |
no_new_nullable |
Off by default. When on, a nullable output column that [[columns]] does not declare is E014. A contract that sets it and declares no [[columns]] is also E014, because there is no baseline. |
| Code | Severity | Meaning |
|---|---|---|
E010 |
Error | Required column missing from the model output |
E011 |
Error | Column type mismatch |
E012 |
Error | Nullability violation: the contract says non-nullable, the model says nullable |
E013 |
Error | Protected column removed |
E014 |
Error | Undeclared nullable column while no_new_nullable is on |
W010 |
Warning | The contract defines a column that is not in the output and is not required |
W011 |
Warning | A contract exists for a model not found in the project |
A column can end up with type Unknown. The compiler could not infer its type, so no type check against a contract runs. Rocky reports the column as I003 at info severity, which changes no exit code. To refuse such a column, run with --strict-contracts or set [contracts] strict = true. Each I003 then becomes the error E059. Who Enforces What says how to give the compiler the types it needs.
rocky test
Section titled “rocky test”rocky test compiles your models and runs them on a local DuckDB. It needs no warehouse connection.
- Compile. Rocky runs the full pipeline: load, resolve, semantic graph, type check, contracts.
- Execute. Rocky runs each model’s SQL on in-memory DuckDB, in dependency order.
- Validate. Where a contract exists, Rocky checks the output schema. It reports the compile diagnostics too.
- Report. Rocky prints a pass or fail line per model.
rocky test --models models/rocky test --models models/ --contracts contracts/rocky test --models models/ --model orders_summary # one modelrocky test --models models/ --output json # total, passed, failed, failures[]Unit tests ([[test]])
Section titled “Unit tests ([[test]])”A unit test feeds a model mocked input rows and asserts on the rows it produces. It never touches the warehouse. It runs on the default rocky test path.
A unit test lives in the model’s .toml sidecar. It names the test, mocks inputs under [[test.given]], and declares the output under [test.expect]:
[[test]]name = "high_value_orders"description = "Orders over $100 should be flagged as high value"
[[test.given]]ref = "orders"rows = [    { id = 1, amount = 150.0, status = "completed" },    { id = 2, amount = 50.0, status = "completed" },]
[test.expect]rows = [    { id = 1, amount = 150.0, is_high_value = true },]
The runner seeds DuckDB with each [[test.given]] as a table named after its ref. It runs the model’s compiled SQL and compares the result to [test.expect].
| Field | Required | Meaning |
|---|---|---|
name |
Yes | Test name, unique within the model |
description |
No | For readers |
[[test.given]] |
No | A mocked input. ref is the model or source name (it matches from / depends_on). rows is an inline list. Repeat the block for more inputs. |
[test.expect] |
Yes | rows is the expected rows. ordered is an optional boolean. |
- Multiset by default. Order does not matter. Duplicate counts do. Rocky runs
EXCEPT ALLin both directions, so a missing row and an extra row are both reported. ordered = truecompares rows by position, against the declaration order.- Only asserted columns are compared. Extra columns in the model output are ignored.
- Empty
rowsasserts that the model produces no rows for the given inputs.
With any [[test]] block, the --output json payload gains a unit_tests object (total, passed, failed, results[]). A failed result carries model, test, error, and a mismatches array of row-level diagnostics. A failed unit test fails the run with a non-zero exit code, the same as a model-execution failure.
Declarative tests ([[tests]])
Section titled “Declarative tests ([[tests]])”A declarative test asserts a fact about data already in the warehouse. It uses the same assertion kinds as the pipeline assertions below. Write [[tests]] in a model sidecar:
[[tests]]type = "not_null"column = "customer_id"
[[tests]]type = "accepted_values"column = "status"values = ["pending", "shipped", "delivered"]severity = "warning"
Run them with --declarative. They execute on the configured warehouse adapter, not DuckDB, so they need a rocky.toml and a warehouse Rocky can reach.
rocky test --declarativerocky test --declarative --pipeline silver # that pipeline's models, on its warehouserocky test --declarative --model orders_summaryWith no --pipeline and no --models, each transformation pipeline runs the tests of its own models, against the warehouse that pipeline targets. Each assertion compiles to a query in the adapter’s dialect. Rocky reports pass, fail, or error. A failed error-severity assertion (the default) exits non-zero. A warning reports without failing the run. The --output json payload carries a declarative summary with the SQL that ran.
rocky ci
Section titled “rocky ci”rocky ci is built for a CI system. It returns a non-zero exit code on failure.
rocky ci --contracts contracts/With no --models, it covers every transformation pipeline in rocky.toml. --models <PATH> limits it to one directory. All three steps must pass.
- Seed. Run
data/seed.sql, when the project has one, in an in-memory DuckDB. - Compile. Run the full compiler, typed from the seed’s tables. This covers type checking and contracts.
- Test. Run every model in that database, upstream pipelines first.
| Exit code | Meaning |
|---|---|
| 0 | All checks passed |
| 1 | Compilation or tests failed: type errors, contract violations, or models that failed to run locally |
Warnings do not change the exit code. The JSON exit_code is the number the process exits with. The JSON also carries compile_ok, tests_ok, models_compiled, tests_passed, tests_failed, diagnostics, and failures.
Pipeline-level checks
Section titled “Pipeline-level checks”Configure these per pipeline in rocky.toml. They run after each table is replicated.
[pipeline.bronze.checks]enabled = truerow_count = truecolumn_match = truefreshness = { error_after = "24h" }Row count
Section titled “Row count”Compares COUNT(*) between the source and target tables. The check passes when the counts match. Its result carries source_count and target_count.
On Databricks, Rocky batches row count and freshness with UNION ALL. Without batching, N tables cost 5N queries. With up to 200 tables per query, a typical pipeline costs about 3. No other warehouse batches these two checks. Snowflake and BigQuery batch the schema describe only. Every other adapter runs one query per table.
Anomaly detection
Section titled “Anomaly detection”Compares this run’s target row count against the table’s recent history in the state store. A deviation above anomaly_threshold_pct (default 50) goes into the run’s anomalies list. An anomaly is a warning, not a failed run. A row-count swing is often real business behavior.
The detector runs for a table only when all of these are true:
- Row-count checks are on for the pipeline.
- At least one table in the batch was checked for row counts.
anomaly_threshold_pctis above 0. A value of 0 or less switches detection off.- The run has a state store, which holds the history.
- This table’s row count was measured, and its history could be read.
rocky run reports per table whether the detector looked, in anomaly_evaluated (table, evaluated, and not_evaluated_reason when false). Read it with anomalies:
anomalies: [] + evaluated: true ──► the count is normalanomalies: [] + evaluated: false ──► nothing was measured; the reason says whynot_evaluated_reason names one missing condition, not all of them, because the remedies differ.
Column match
Section titled “Column match”Compares the source and target column sets, ignoring case. It reports each missing or extra column. Rocky reads both column lists again after the copy, so the check costs two extra metadata queries per table. It sees the schema the copy produced, including a column the run added.
A failed read is retried once, only when the adapter classifies the failure as retryable and it is not a rate limit. A rate limit, a permanent error, or a second failure reports the check as not evaluated.
Freshness
Section titled “Freshness”Compares MAX(timestamp_column) against the current time. A table older than error_after fails at error severity. A table older than warn_after fails at warning severity. Both levels use a duration such as "12h" (see Freshness durations). The result carries lag_seconds and threshold_seconds. If freshness matters for a table, confirm its timestamp_column is populated.
Rocky does not always measure freshness:
| Case | Result |
|---|---|
| The table is empty | No freshness check. MAX() is NULL over no rows. |
| The table has rows but the timestamp column holds no value | A failed freshness_not_evaluated check. Its reason gives the row count. |
| The query fails, or returns a cell Rocky cannot read as a timestamp or a count | The same failed freshness_not_evaluated check. |
prune_unchanged is on, the adapter reports a source change-marker, and the source has not changed |
No query. The table skips its data checks, freshness included. The check is absent from the JSON. Schema drift covers pruning. |
prune_unchanged is off by default. An absent check looks the same as a table with no freshness configured: it is absent, not failing.
Dagster fills the gap differently. In Pipes mode the check is absent, as in the JSON. Outside Pipes mode a configured check has a declared spec, so Dagster adds a placeholder:
| Cause | Placeholder |
|---|---|
| The table was pruned | It carries forward the last verdict, or passes with a note that it was never checked. |
| The table was checked and produced no freshness result | It fails at WARN severity, marked not produced by rocky. |
| The table was never materialized | It fails at WARN severity, with its own reason. |
Null rate
Section titled “Null rate”Samples the table with TABLESAMPLE (N PERCENT) and works out the null percentage per column. It never scans the whole table.
null_rate = { columns = ["email"], threshold = 0.05 }Custom SQL
Section titled “Custom SQL”Your SQL, with a {target} placeholder that Rocky replaces at run time. The check passes if the query result is less than or equal to the threshold.
custom = [ { name = "no_future_dates", sql = "SELECT COUNT(*) FROM {target} WHERE date > CURRENT_DATE()", threshold = 0 }]Rocky does not gate a custom sql query. It runs the query as written. Treat a custom check as code you run.
Assertions in a run
Section titled “Assertions in a run”An assertion is a repeated [[assertions]] block under [pipeline.<name>.checks]. The same block in a model sidecar is [[tests]]. Each block declares a type, and may declare column, severity, filter, and the parameters its type needs. The set matches the assertion surface of Databricks Labs’ DQX.
[[pipeline.silver.checks.assertions]]type = "not_null"column = "order_id"
[[pipeline.silver.checks.assertions]]type = "in_range"column = "amount_cents"min = "0"max = "100000000"filter = "region = 'US'"
Assertion kinds
Section titled “Assertion kinds”| Type | Level | Parameters | Passes when |
|---|---|---|---|
not_null |
row | none | The column has no NULL. |
unique |
set | none | The column has only unique values. |
unique_expr |
set | key_expr |
A computed key is unique (GROUP BY <expr> HAVING COUNT(*) > 1). Use it when neither unique nor composite can express the identity. NULL keys are not excluded. Use filter to scope them out. |
accepted_values |
row | values |
Every non-NULL value is in the set. |
relationships |
row | to_table, to_column |
Every non-NULL value exists in to_table.to_column. |
expression |
row | expression |
The SQL boolean predicate holds per row. It is one expression over the row’s own columns. It calls only allowlisted pure scalar functions. It has no subquery and no qualified function. |
row_count_range |
table | min, max (optional) |
The row count is in the inclusive range. |
in_range |
row | min, max (optional, numeric) |
Values are in the numeric range. NULLs pass. |
regex_match |
row | pattern |
The column matches the dialect regex. NULLs pass. The pattern allows no single quote, backtick, or semicolon. |
aggregate |
table | op, cmp, value |
op(column) cmp value is TRUE. op is sum, count, avg, min, or max. cmp is lt, lte, gt, gte, eq, or ne (or symbolic aliases). |
composite |
set | kind: "unique", columns |
A column tuple is unique. It needs at least two columns. Use unique for one. |
not_in_future |
row | none | The timestamp is not in the future (col <= CURRENT_TIMESTAMP()). NULLs pass. |
older_than_n_days |
row | days |
Every timestamp is at least days old. NULLs pass. |
Seven row-level kinds are quarantinable: not_null, accepted_values, expression, in_range, regex_match, not_in_future, older_than_n_days. See Row quarantine. The set, table, and referential kinds (unique, unique_expr, composite, row_count_range, aggregate, relationships) run after the fact and cannot be quarantined. relationships needs a join, not a per-row predicate.
Severity and fail_on_error
Section titled “Severity and fail_on_error”Each assertion takes severity: error (the default) or warning. Each pipeline takes fail_on_error, which defaults to true.
| Setting | Effect |
|---|---|
severity = "error" and fail_on_error = true |
A failing assertion fails the run. A replication run that already copied data exits 2 (partial success). A failed quality-pipeline gate exits 1. |
severity = "warning" |
The result has passed = false and severity = "warning". It never fails the pipeline. |
fail_on_error = false |
Every error becomes a non-fatal result. Use it for shadow runs and observation modes. |
For the replication checks, severity describes a check that ran and found a problem. It does not apply to a check Rocky could not run.
A check whose query fails has passed = false and a not_evaluated field that says why. It always has severity = "error", whatever the config says. It fails the run while fail_on_error is on. This holds for every kind: row_count, column_match, freshness, null_rate, [[checks.custom]], [[assertions]], cross_source_overlap, and a quarantine plan Rocky could not compile.
the query answers, the data is bad -> your severity (warning stays advisory)the query never ran -> always error (gates, unless fail_on_error = false)severity = "warning" on freshness means “a stale table is only a warning”. It does not mean “a freshness query I could not run is only a warning”. That is an unknown, not a tolerated result.
Reusable named tests
Section titled “Reusable named tests”To apply one assertion to many models, define it once in models/test_definitions.toml. A definition is any assertion type with its parameters and an optional default column:
[positive_amount]type = "expression"expression = "amount > 0"A model applies it with a [[use_test]] block. At the use site you may set the column, the severity, and the filter. Inline [[tests]] and [[use_test]] sit side by side:
[[tests]]type = "unique"column = "order_id"
[[use_test]]name = "positive_amount"column = "amount"severity = "warning"
A reference resolves into an ordinary assertion at load. A [[use_test]] that names no definition fails the load with an error, so a typo cannot silently drop a check.
Per-assertion filter
Section titled “Per-assertion filter”Every assertion accepts a filter: a SQL boolean predicate that scopes the check. A row where (filter) is TRUE is checked. A row where it is FALSE or NULL passes.
[[assertions]]type = "in_range"column = "amount_cents"min = "0"filter = "region = 'US' AND status != 'cancelled'"The filter is your SQL and must be valid in the target dialect. Rocky does not rewrite it. Rocky checks it with one gate. The gate covers:
- an assertion’s
filterandexpression; - a
unique_exprkey_exprand across_source_overlapkey_expr; - the same
expressionandfilterwhen quarantine lowers the assertion into its own statements; - a
metadata_columns[].value; - a check an agent drafts through the
draft_checkMCP tool. Rocky validates under the target adapter’s dialect before it writes. With several pipelines, it infers the dialect when they all agree. Otherwise passpipeline.
Rocky parses the fragment under the target dialect. It accepts exactly one expression over the row’s own columns. It refuses:
- anything after that one expression, so the fragment cannot close Rocky’s wrapping parenthesis and add clauses;
- any subquery, in any position;
- any qualified function name, such as
schema.fn(...). That is how user-defined, remote and plugin functions are reached; - any function not on Rocky’s allowlist of pure scalar functions;
- a lambda;
- a placeholder (
$name,$1,?), and an unquoted session-identity word such ascurrent_user,session_user,current_role,current_catalogorcurrent_warehouse. Each reads session state, not the row.
Before that, Rocky refuses a fragment that could end the query it builds, or that the five target dialects do not lex the same way:
- a
;outside a string literal, a quoted identifier or a comment, including a trailing one; - an unbalanced quote, or a
/* */comment that never closes; - a backslash inside a quoted literal, a triple-quoted string, a
$$…$$dollar quote, a backtick, a//or#line comment, or a nested/*. Snowflake, Databricks, BigQuery, DuckDB and Trino do not agree on these, so Rocky refuses rather than guess.
Comparisons, CASE, CAST, BETWEEN, IN (...) with literals, and functions such as coalesce, nullif, abs, round, length, lower, upper, trim, regexp_like, md5 and date_trunc pass. Functions that read a file, a secret, a session variable or a remote endpoint do not, whatever their name looks like. DuckDB’s read_text, Snowflake’s GETVARIABLE and Databricks’ secret are refused by name. random() and uuid() are not on the allowlist, so they are refused in every position.
The allowlist checks a function’s name, not the code behind it. A warehouse can let a session rebind a built-in under an unqualified call. Then an allowlisted call runs the rebound body. Rocky measured this per dialect:
| Dialect | Unqualified rebind wins over the built-in? | Measured on |
|---|---|---|
| DuckDB | Yes. It shadows the built-in, even for a new session. | v1.5.5, persistent file |
| Databricks | No. A qualified override exists, but Rocky refuses qualified names. | Unity Catalog |
| Snowflake, BigQuery, Trino | Not probed. | No sandbox available |
On a persistent, file-backed DuckDB, creating that binding needs the file-write access that already lets you edit the data. So the allowlist is not a boundary against that admin. Rocky’s in-memory DuckDB, Snowflake, BigQuery and Trino have not been probed, so the same privilege link is not established for them.
Six allowlisted names are refused in one shape, because that shape reads a Snowflake session parameter:
| Function | Refused | Accepted |
|---|---|---|
to_date, to_timestamp, to_char |
One argument, such as to_date(order_date). It reads a session default format. |
An explicit format, such as to_date(order_date, 'YYYY-MM-DD') |
date_trunc, datediff (and date_diff) |
A week part or synonym (w, wk, weekofyear, woy, wy). It reads WEEK_START. |
Any other part, such as day, month, year, or the Monday-start week_iso |
date_part |
A week part or synonym reads WEEK_START. A dayofweek (weekday, dow, dw) or yearofweek part reads WEEK_OF_YEAR_POLICY and WEEK_START. |
Any other part, including dayofyear, the epoch_* and timezone_* parts, and the ISO-fixed week_iso, dayofweekiso, yearofweekiso |
EXTRACT(<part> FROM <expr>) is refused on the same three part families. On Snowflake, EXTRACT(<part>, <expr>) is refused too. It parses as its own construct, not a function call.
Two key positions add a rule:
| Position | Extra rule |
|---|---|
unique_expr key_expr, cross_source_overlap key_expr |
No clock function (now(), current_timestamp) and no COLLATE. A value that changes between evaluations is not a key. A collation changes what equality means. |
quarantine expression or filter, not_in_future, older_than_n_days |
A clock function such as now() is accepted in every mode. split evaluates each predicate once, so a clock read cannot put a row in both outputs. |
The gate runs before anything executes. What a refusal does depends on the field:
| Field | A refusal |
|---|---|
An assertion filter or expression, a key_expr |
The check fails at error severity, with a not_evaluated reason naming the field, the table and the construct to remove. |
A quarantine expression or filter |
The check quarantine:compile fails the same way. No quarantine table is written. The run fails, whatever fail_on_error says. |
metadata_columns[].value |
The config load fails, so no command runs. |
The draft_check MCP tool |
The tool refuses the write. The bad check is never saved. |
Row quarantine
Section titled “Row quarantine”A row-level assertion can move its failing rows aside instead of only counting them. Configure quarantine on a quality pipeline. Rocky ignores the block on any other pipeline type. [checks.quarantine] takes only enabled, mode and the two suffixes.
[pipeline.silver.checks.quarantine]enabled = truemode = "split" # or "tag" or "drop"| Mode | Behavior |
|---|---|
split |
Rocky writes <target>__valid (passing rows) and <target>__quarantine (failing rows, plus an _error_<name> label column per assertion). When the run completes, and the two suffixes name two different tables, each row lands in exactly one. <target> is untouched. Point downstream models at <target>__valid. Not available on Trino. |
tag |
Rocky rewrites <target> in place and adds an _error_<name> column per assertion. It is populated on failing rows and NULL on passing rows. Every row stays. It rewrites the source, so use it with care on a raw replication target. Not available on Trino. |
drop |
Rocky writes only <target>__valid. It discards failing rows. The quarantine count is still in check_results[]. On Trino, Rocky drops the previous valid table before it creates the new one. |
Rocky builds the quarantine predicate from every quarantinable assertion, joined with AND. A filter composes as CASE WHEN (filter) THEN base_valid_pred ELSE TRUE END. An out-of-scope row stays on the valid side, even when the base predicate would fail it. Set, table, and referential assertions always run as after-the-fact checks, whatever the mode.
split evaluates the predicate once. It writes the source rows plus one label column per assertion to _quarantine_labels_<token> in the source’s schema. It builds __valid and __quarantine from those labels, then drops the label table. The token is a random UUID for each run. A run killed between those statements leaves the label table behind. Two runs of one pipeline at the same time can still overwrite each other’s __valid and __quarantine.
__valid keeps exactly the source’s columns. Rocky writes it with SELECT * EXCLUDE (...) on DuckDB and Snowflake, and SELECT * EXCEPT (...) on Databricks and BigQuery. A dialect with no such form refuses split with a quarantine:compile check. Trino is one, and so is any adapter whose dialect lacks it.
Rocky never overwrites a column it cannot prove it wrote. Before any statement runs, it reads the source’s columns and compares each label name with them, ignoring case.
splitrefuses any source column named like a label. It never writes its source, so the column is not Rocky’s.tagrewrites its own source, so the second run sees the first run’s labels. After each successfultag, Rocky records in the state store the label columns it wrote and the table’s full column list. On the next run it replaces a recorded column, but only while the table still has exactly the recorded columns. Appended or updated rows keep that true. A table that was replaced, or gained or lost a column, does not. Its label columns are refused.- If the state store is lost, nothing proves ownership, so
tagrefuses. This includes every existingtagtable on its first run after an upgrade. Remove the column, and the next run writes and records it again.
A refusal names the column and the label. Rename or remove the column, or give the assertion a name so its label is _error_<name>. Where the warehouse cannot drop or rename a column (a Databricks table without column mapping, say), rebuild the table without it.
Every name quarantine creates must fit in 255 characters, the identifier limit of Snowflake and Databricks. This covers the suffixed tables and the label columns. A longer name is refused with a quarantine:compile check before any statement runs.
A quarantine that fails or is refused fails the run, whatever fail_on_error says. The table counts in tables_failed and is listed in errors. What it leaves behind depends on when it failed:
- Refused (
quarantine:compile): nothing runs and no table is written. Downstream reads the previous run’s rows. - Failed at the warehouse (
quarantine:execute): the check names the statement’s role and the warehouse error.splitruns the label table, then__quarantine, then__valid, then the drop. Finished statements keep what they wrote, so__quarantinecan be new while__validis the previous run’s. Rocky still tries to drop the label table. A failed drop leaves it behind. A statement that times out may still have committed.
Output
Section titled “Output”Every assertion writes one check_results[] entry in the rocky apply JSON:
{ "name": "not_null:order_id", "passed": false, "severity": "error", "kind": "not_null", "column": "order_id", "failing_rows": 3}The name is the assertion’s own name, or else "{kind}:{column}". Pipeline-level checks and assertions share this shape, so an orchestrator does not need to tell them apart. See the JSON Output reference.
Cross-source overlap
Section titled “Cross-source overlap”Assertions check one table at a time. They miss one duplication: the same business key arrives through two sources that are later UNION-ed into one target. Each source is unique, so every unique check passes. The target still double-counts every shared key. cross_source_overlap catches this.
[pipeline.bronze.checks.cross_source_overlap]keys = ["order_id"] # or: key_expr = "md5(a || '-' || b)"severity = "warning"max_overlap_rows = 0 # any overlap fails; raise to tolerate a known setsample = 20 # overlapping keys attached to the resultGive exactly one of keys (a column tuple) or key_expr (a SQL expression). key_expr goes through the same gate, including the key-position rules under Per-assertion filter.
The runner groups the pipeline’s managed source tables into sibling groups. Siblings share a source type and a table name, and landed in more than one target schema. Rocky tags each sibling’s rows with its source and runs:
SELECT order_id, COUNT(DISTINCT _src) AS _n_srcFROM ( SELECT order_id, '<table_1>' AS _src FROM <table_1> WHERE order_id IS NOT NULL UNION ALL SELECT order_id, '<table_2>' AS _src FROM <table_2> WHERE order_id IS NOT NULL -- one arm per sibling) _uGROUP BY order_idHAVING COUNT(DISTINCT _src) > 1COUNT(DISTINCT _src) counts the distinct sources a key appears in. One source’s own duplicates never raise a flag. With a key_expr or multi-column keys, the key list changes to match.
Rocky skips a sibling table it cannot evaluate, because the key column is missing or the table is keyless. It logs the reason and does not fail the check. The result is named cross_source_overlap:<source_type>.<table>:
{ "name": "cross_source_overlap:shopify.orders", "passed": false, "severity": "warning", "overlap_count": 3, "contributing_tables": ["raw__us__shopify.orders", "raw__eu__shopify.orders"], "sample": ["ord_1001", "ord_1002", "ord_1003"]}Rocky counts how many siblings in a group carry the key. Then it splits three ways:
0 siblings carry the key -> not evaluated, error severity, fails (a typo)1 sibling carries it -> passes, your severity, does not gate (nothing to compare)2 or more carry it -> measured across those siblings, and it can failA group of three where two share a duplicate key still fails, even if the third has no such column. A group whose query failed, or whose key expression was refused, is an unevaluated failure like every other kind.
Rocky catches cross-source duplication at two points:
| Layer | Mechanism | Runs | Config |
|---|---|---|---|
| Preventive | on_collision |
rocky discover, before a stray catalog is created |
[pipeline.NAME.source.discovery] on_collision → collision_candidates |
| Detective | cross_source_overlap |
rocky run, after the sibling tables are written |
[pipeline.NAME.checks.cross_source_overlap] |
The preventive layer needs an adapter that resolves external object ids, such as Fivetran, and inspects connector metadata. The detective layer works on any warehouse, because it queries the written tables. Use both. Use the detective check alone if your sources expose no object ids at discover time. See discovery configuration.
AI-generated tests
Section titled “AI-generated tests”rocky ai-test generates assertions from a model’s intent and schema. See AI and Intent. Each generated assertion is a SQL query that returns 0 rows when it holds:
-- test: orders_summary_no_null_customer_idSELECT * FROM warehouse.silver.orders_summary WHERE customer_id IS NULLGenerated tests cover not-null keys, grain uniqueness, value ranges, and referential integrity. Rocky saves them to a tests/ directory.
Typical loop
Section titled “Typical loop”- Write a model and a contract.
- Run
rocky testlocally. - Push. CI runs
rocky ci. - Optionally run
rocky ai-test --savefor more assertions.