

Schema Drift
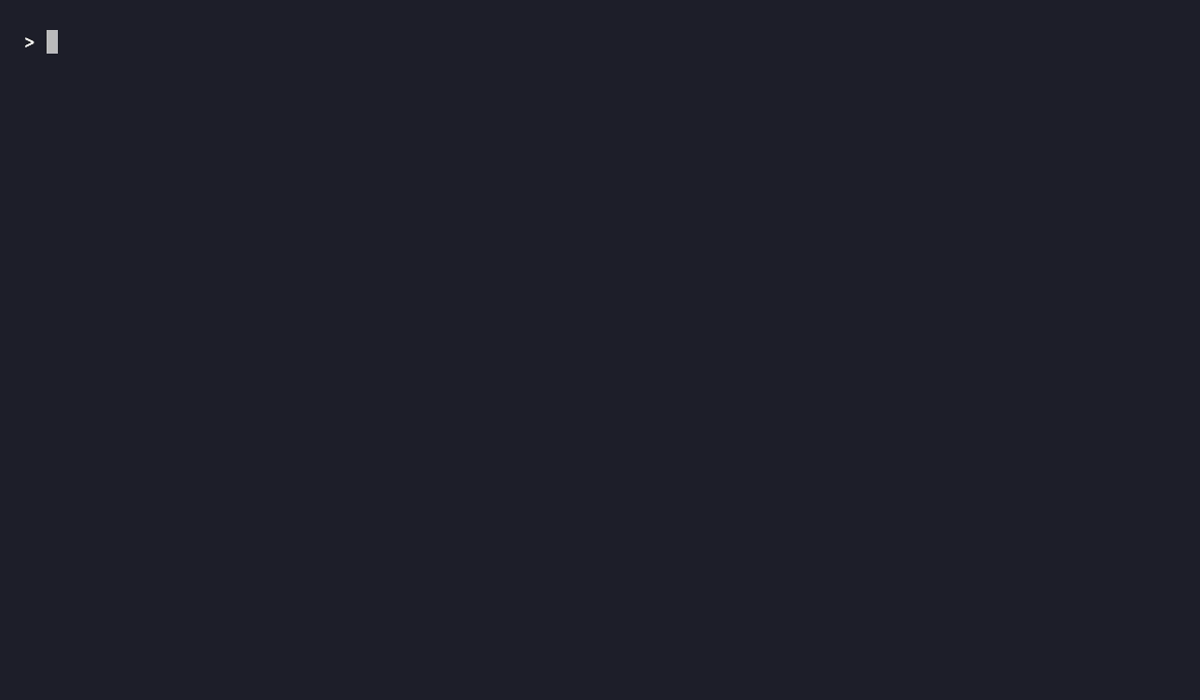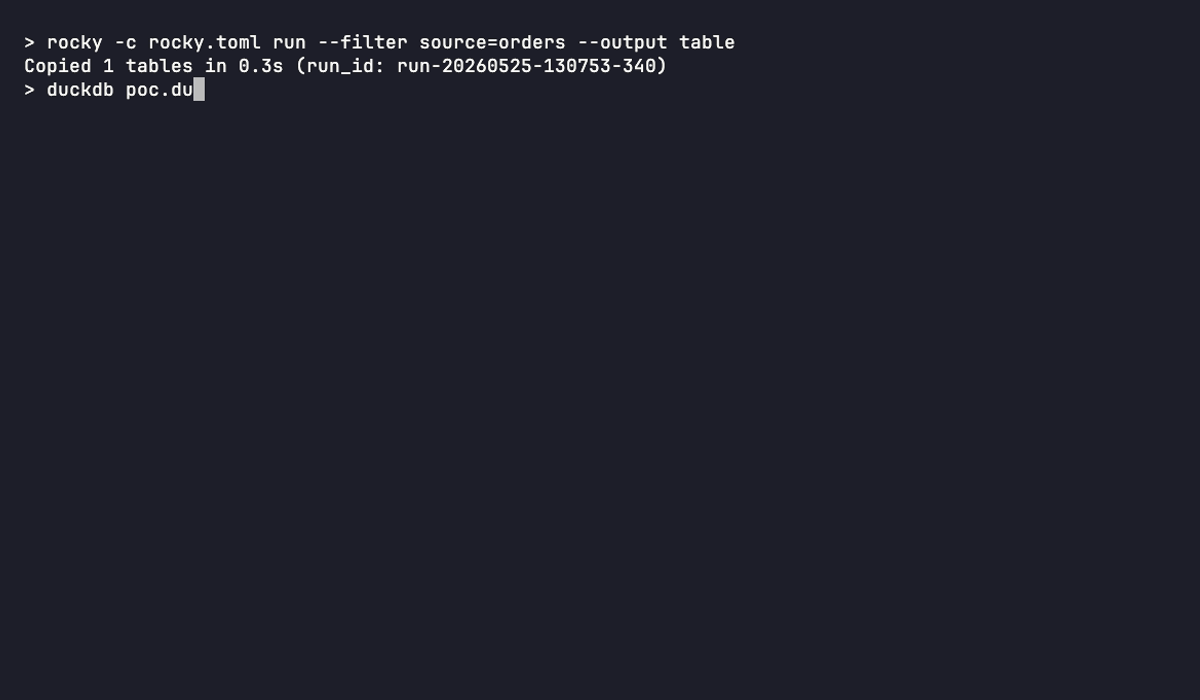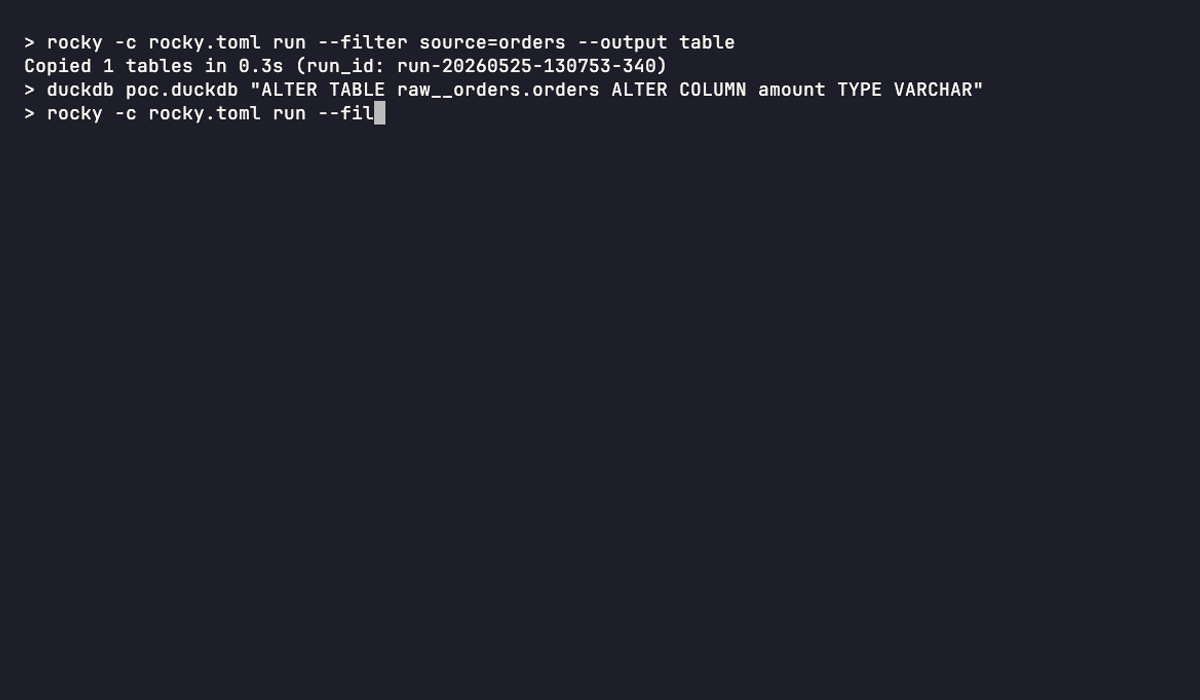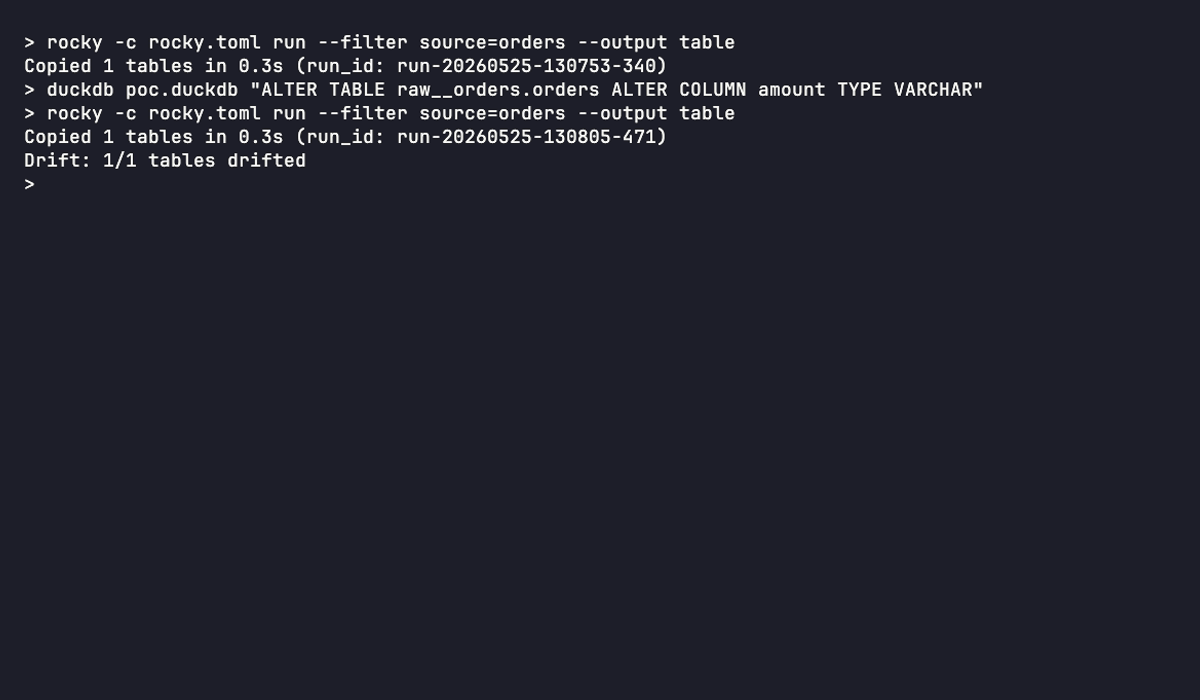
Schema drift is a column whose type in the source no longer matches its type in the target table. Rocky checks for it as it copies each table, and fixes what it safely can. This is graduated evolution: a safe widening becomes an ALTER TABLE that keeps the data, and anything else becomes a full refresh.
What It Detects
Section titled “What It Detects”Drift in Rocky means column type mismatches between the source and the target. A column that is STRING in the source and INT in the target has drifted. So has an INT that widened to BIGINT.
How Rocky classifies and resolves a change
Section titled “How Rocky classifies and resolves a change”Rocky runs the check inside each table’s copy, whenever the target already exists.
per table, when the target already exists │ ├─► DESCRIBE TABLE source ─┐ │ ├─► compare types, case-insensitive └─► DESCRIBE TABLE target ─┘ │ ▼ ┌───────────────────┐ │ any type changed? │ └──┬─────────────┬──┘ no │ │ yes ▼ ▼ copy the rows ┌────────────────┐ │ safe widening? │ └──┬──────────┬──┘ yes │ │ no ▼ ▼ ALTER TABLE ALTER COLUMN DROP TABLE IF data preserved EXISTS, then full refreshTwo cases bypass the check.
-
The source has not changed and
prune_unchangedis on. This opt-in optimization skips the whole table when the source reports the same change-marker as the last successful copy. That skips the copy, the drift check, and the data checks. Rocky re-evaluates drift once the source changes again.Three things have to line up, so a table you expect to be pruned may still be copied. The adapter has to offer a change-marker at all — one that cannot says so, and Rocky copies.
--no-pruneon the command line turns it off for that run. And anincrementaltable is never pruned until it has a recorded watermark, so its first run always copies. -
DESCRIBE TABLEfails. Rocky swallows the error instead of failing the run. It treats an unreadable target as absent and rebuilds it with a full refresh. An unreadable source produces no drift result for that run, so the copy proceeds unchecked.
Graduated Evolution
Section titled “Graduated Evolution”Safe Type Widenings
Section titled “Safe Type Widenings”These type changes keep the data. Rocky applies them with ALTER TABLE and skips the full refresh:
| From | To | Example |
|---|---|---|
INT |
BIGINT |
Integer widening (also TINYINT/SMALLINT upward) |
FLOAT |
DOUBLE |
Float precision widening |
DECIMAL(p1, s) |
DECIMAL(p2, s) |
Decimal precision increase (p2 > p1, same scale) |
VARCHAR(n1) |
VARCHAR(n2) |
String length increase (n2 > n1) |
numeric / BOOLEAN |
STRING |
Representation change (lossless) |
ALTER TABLE acme_warehouse.staging__us_west__shopify.ordersALTER COLUMN amount TYPE DECIMAL(12, 2)Classification is per-dialect. The table above is the engine’s default allowlist, verified end-to-end on DuckDB. Four warehouses override it with narrower rules that match what their own ALTER COLUMN accepts. A change outside a warehouse’s rules falls through to a full refresh.
- Snowflake allows
NUMBER(p,s)precision widening andVARCHARlength widening, and nothing else. ItsDESCRIBE TABLEoutput canonicalizes every integer type toNUMBER(38,0), so integer widening never surfaces as drift there. - BigQuery allows
INT64 → NUMERIC,INT64 → BIGNUMERIC, andNUMERIC → BIGNUMERIC, and nothing else. A numeric →STRINGchange is not assignable on BigQuery. - Databricks allows integer → wider integer,
TINYINT/SMALLINT/INT→DOUBLE,FLOAT→DOUBLE, andDECIMALprecision widening at the same scale. Rocky turns on Delta’s type-widening table feature (delta.enableTypeWidening, DBR 15.4 LTS or later) before theALTER. Delta never accepts numeric →STRING. - Trino allows
INTEGER → BIGINT,REAL → DOUBLE, andDECIMALprecision widening at the same scale, with theSET DATA TYPEform. These are the Iceberg connector’s rules.
Unsafe Type Changes
Section titled “Unsafe Type Changes”Any type change outside the safe allowlist costs a full refresh. Rocky drops the target and rebuilds it from the source:
DROP TABLE IF EXISTS acme_warehouse.staging__us_west__shopify.orders-- followed by full refresh from sourceExamples: STRING to INT, BIGINT to INT (narrowing), DATE to TIMESTAMP.
What Is NOT Drift
Section titled “What Is NOT Drift”- New columns in the source. Rocky adds them rather than treating them as drift. Before the copy it issues one
ALTER TABLE ADD COLUMNper new column, each nullable, so historical rows keepNULL. The run reports anadd_columnsaction. - Columns removed from the source. The drift check does not flag a target column the source no longer has. It does not schedule a DROP COLUMN for that column, and there is no opt-in for that today. A full refresh, covered above, can still discard it: it rebuilds the table from only the source’s current columns.
Output
Section titled “Output”Drift detection runs inline on a replication run. Rocky reports what it did in the drift section of the run JSON output:
{ "drift": { "tables_checked": 45, "tables_drifted": 1, "actions_taken": [ { "table": "acme_warehouse.staging__us_west__shopify.events", "action": "drop_and_recreate", "reason": "column 'status' changed STRING -> INT" } ] }}Run rocky plan to preview the SQL, including any drop statements, without executing it:
rocky plan --filter client=acme --output jsonThe run output surfaces three actions:
| Action | What Rocky did |
|---|---|
alter_column_types |
Every drifted column passed the safe-widening check, so Rocky altered them in place. |
drop_and_recreate |
At least one change was incompatible, so Rocky rebuilt the target from the source. |
add_columns |
Rocky added source-only columns to the target. |
By default Rocky applies these mutations automatically. The opt-in drift-governance gate (auto_apply_additive_drift plus a [policy] grant for schema_change.additive) narrows that. Only provably additive, policy-allowed changes proceed. Rocky refuses anything else before it touches the target, and reports a require-review failure for that table.